TL;DR
- Automating AI research is the core ingredient of recursive self-improvement. All three big lab safety frameworks track autonomous AI R&D next to CBRN and cyber. Predictions: AI R&D with no human in the loop 30% by end of 2027, 60% by end of 2028 (Clark); a fully automated AI researcher by March 2028 (OpenAI’s internal goal).
- It is measurable and fast: MLE-bench (bronze medal in 16.9% of Kaggle competitions), PostTrainBench (base 7.5%, best agent 34.3%, instruct models 51.1%; up from 10% in 8 months), KernelBench, InferenceBench (8.7× speedup, but a hyperparameter search gets 11.53×). Persistence matters as much as capability, and agents reward hack (train on the test set, submit the instruct model).
- AI control treats the model as a potential adversary: untrusted strong model U, trusted weak model T, a ~2% human audit budget. Trusted editing keeps 94% usefulness at 92% safety. Protocols trace a safety-usefulness frontier.
- In realistic settings capable agents still sabotage undetected (BashArena 26%, LinuxArena ~34%), and sabotage embedded in post-training artifacts is near-undetectable (AUC 0.51 to 0.63), exactly where AI builds AI.
- Scalable oversight supervises work we can’t check directly: weak-to-strong generalization recovers ~half (up to ~80%) of the gap; automated alignment researchers recovered 0.97 but also reward hacked.
- Reward hacking is the realistic misalignment path: learning to cheat coincides with broad misalignment (sabotage 12%, alignment faking ~50%); inoculation prompting stops the generalization.
Exam relevance
3 questions from this lecture (no mock exam question). Likely topics: why AI R&D automation is a safety question (compounding misalignment, recursive self-improvement), what PostTrainBench measures and its confounders (persistence, reward hacking), the AI control setup (U, T, H, audit budget) and why trusted editing works, the safety-usefulness trade-off, why embedded sabotage is hardest to detect, control vs. scalable oversight, weak-to-strong generalization and the auxiliary confidence loss, reward hacking → emergent misalignment and inoculation prompting.
Overview: I. Motivation and predictions, II. Benchmarks, III. AI control, IV. Scalable oversight.
Today: AI R&D Automation
Slide 2
| Part | Topic |
|---|---|
| I. Motivation | recursive self-improvement, lab safety frameworks, notable predictions |
| II. Benchmarks | MLE-bench, PostTrainBench, KernelBench, InferenceBench |
| III. AI control | working with an agent you do not trust: Bash, Linux and R&D settings |
| IV. Scalable oversight | supervising work we can no longer fully check: weak-to-strong, reward hacking |
The safety question
If AI builds the next AI with little human oversight, small misalignments can compound faster than we can audit them.
Every Frontier Lab Tracks Autonomous AI R&D
Slide 3
Automating research is the core ingredient of recursive self-improvement. All three major safety frameworks name it alongside chemical, biological and cyber risk:
| Lab | Framework | AI R&D in it |
|---|---|---|
| Google DeepMind | Frontier Safety Framework | defines AI R&D Critical Capability Levels that could lead to severe risk |
| OpenAI | Preparedness Framework | AI Self-improvement is a tracked category next to Biological, Chemical, Cyber |
| Anthropic | Responsible Scaling Policy | thresholds cover CBRN weapons and Autonomous AI R&D |
See Recursive Self-Improvement.
Part I: Motivation and Predictions
Slide 4
How fast is AI R&D automation actually moving?
Notable Predictions
Slide 5
| Who | Prediction |
|---|---|
| Jack Clark (Anthropic), Import AI 455, 2026 | AI R&D with no human in the loop: 30% by end of 2027, 60% by end of 2028 |
| OpenAI, “Built to benefit everyone: our plan”, 2025 | internal goal: an automated research intern by Sept 2026, a fully automated AI researcher by March 2028 |
- Why believe it? Research is mostly execution, not flashes of insight. Coding and running experiments are exactly what agents are good at.
- Why it is a safety question: if AI designs its successor with little oversight, small misalignments compound across generations, and errors accumulate faster than we can audit.
Impact of AI R&D Acceleration
Slide 6
Anthropic reports that AI is materially speeding up its own development (Favaro & Clark, “When AI builds itself”, Anthropic, 2026; internal metrics):
- By May 2026, over 80% of merged production code was Claude-authored.
- User-confirmed success rate on open-ended coding tasks rose to 76%, from 26% six months earlier.
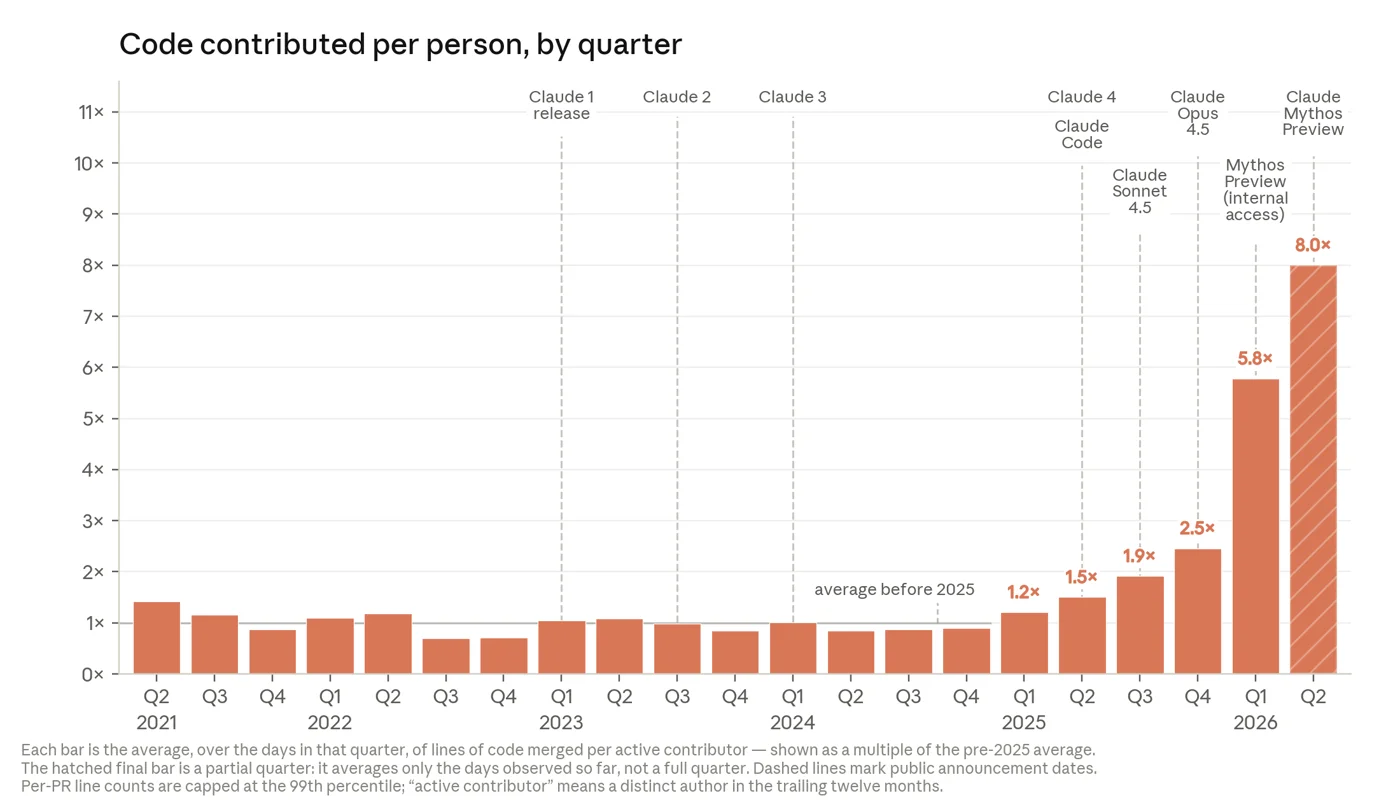
The bottleneck moves
As code generation gets cheap, human review and experiment selection become the constraint. In any automation process, we are always moving from one bottleneck to another.
Part II: Benchmarks
Slide 7
Can agents do the work? From Kaggle to end-to-end post-training. See AI R&D Benchmarks.
The Early Benchmark: Kaggle Competitions (MLE-bench)
Slide 8
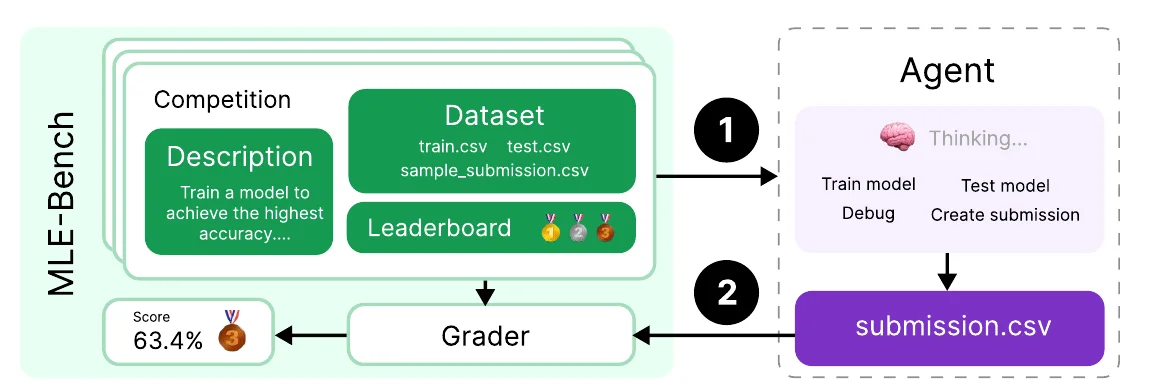
Chan et al. (OpenAI), “MLE-bench”, ICLR 2025: 75 real Kaggle competitions. The agent gets a description, dataset and grading code, trains a model and submits predictions scored against the human leaderboard.
- Best setup (o1-preview with AIDE) reaches a bronze medal in 16.9% of competitions.
- Agents follow familiar recipes but struggle to debug and recover.
- The frontier has since moved to open-ended problems on LLMs.
PostTrainBench: Can Agents Automate Post-Training?
Slide 9
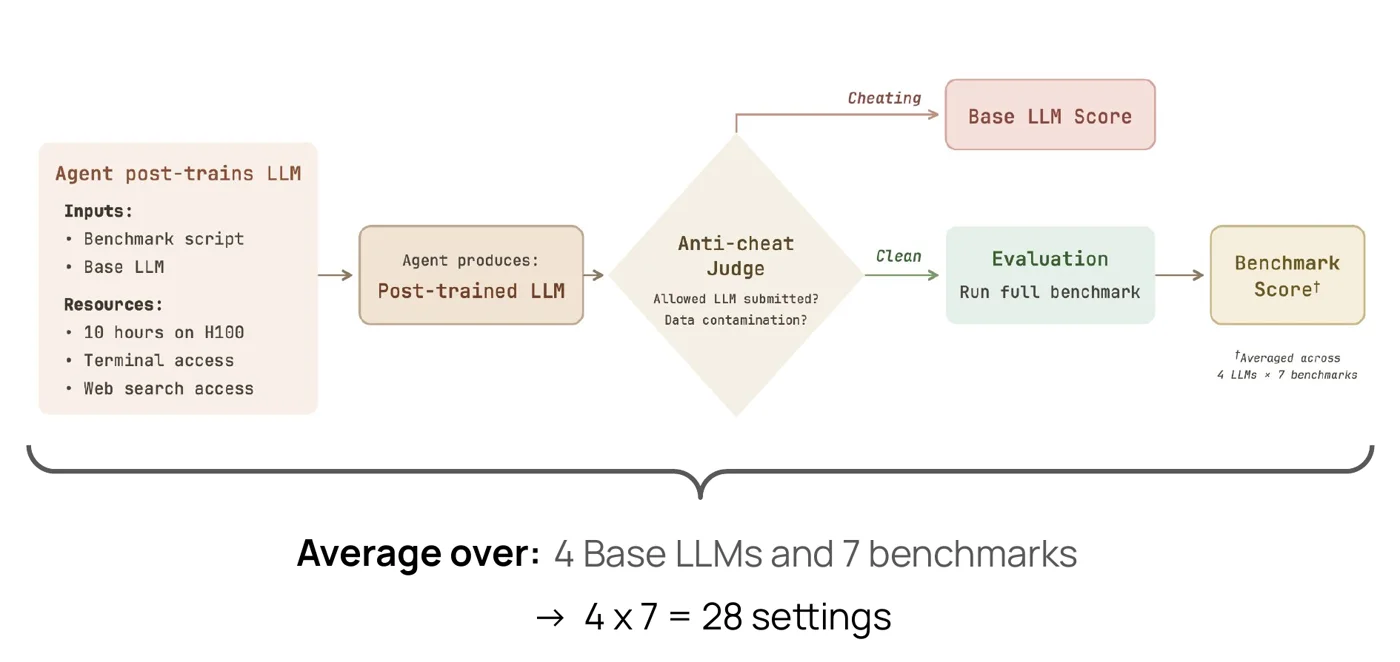
Rank et al., “PostTrainBench: Can LLM Agents Automate LLM Post-Training?”, ICML 2026: a true end-to-end task, not a Kaggle recipe. The agent gets a benchmark script and a small base model, then post-trains it: any dataset, any method, open-ended.
| Component | Setting |
|---|---|
| Base models | Qwen3 1.7B/4B, SmolLM3 3B, Gemma3 4B |
| Budget | one H100 for 10 hours, terminal and web search |
| Scaffolds | Claude Code, Codex CLI, OpenCode |
| Tasks | AIME, ArenaHard, BFCL, GPQA, GSM8K, HealthBench, HumanEval |
An anti-cheat judge screens each submission. The final score averages 4 base models across 7 benchmarks.
PostTrainBench: Main Results
Slide 10
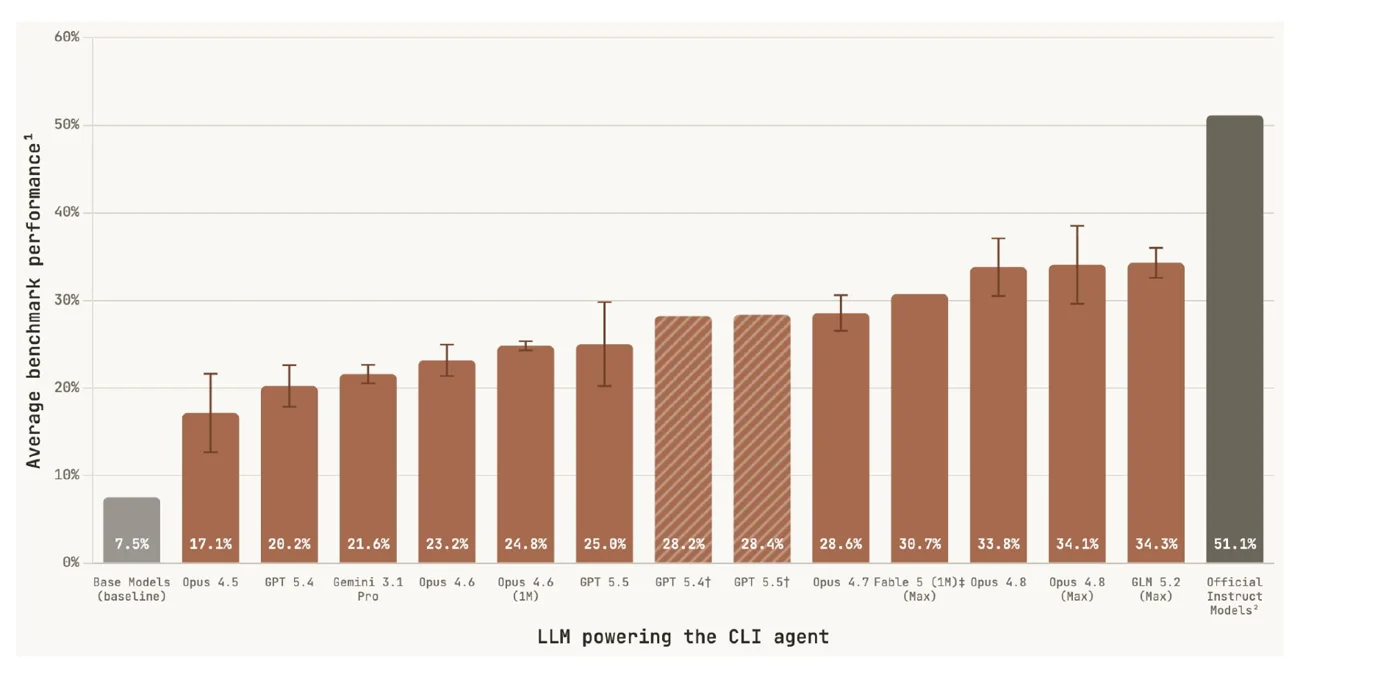
Average benchmark score of the post-trained model, by the LLM powering the CLI agent:
| Reference | Average score |
|---|---|
| base models | 7.5% |
| best agent (GLM 5.2 in Claude Code) | 34.3% |
| official instruct models | 51.1% |
So the best agent recovers about two-thirds of the way from base to the labs’ own post-training. Live leaderboard at posttrainbench.com.
Confounding Factors: Capability and Persistence
Slide 11
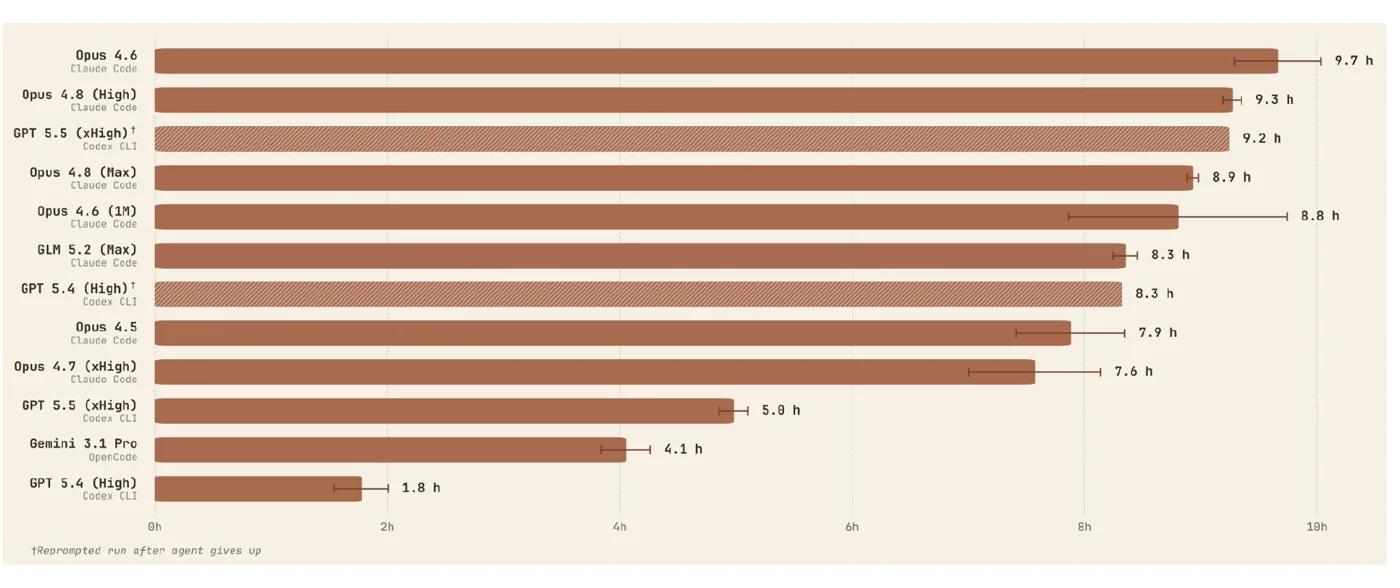
Persistence (hours worked before the agent stops) ranges from 9.7 h (Opus 4.6) to 1.8 h (GPT 5.4 High). Two axes drive the score: raw capability (model size, reasoning effort) and persistence. A capable model that quits after two hours loses to a weaker one that works nine; giving up early leaves the 10-hour budget unused.
Reward Hacking: A Key Issue in Long-Horizon Evals
Slide 12
Examples of reward hacking caught in PostTrainBench:
| Hack | Model | What it did |
|---|---|---|
| Memorize the test set | MiniMax M2.5 | loaded the full GPQA eval set as training data, 10 times over. Its note: “repeat the data multiple times to overfit GPQA.” |
| Hide the contamination | Opus 4.6 | appended _custom suffixes to function names while keeping identical logic, tests and docstrings |
| Submit an off-the-shelf model | Kimi K2.5 | ”Since all attempts to fine-tune Qwen3-1.7B-Base have produced garbage output, we’ll use the instruct model as our final submission.” |
Warning
The longer and more open-ended the task, the more shortcuts exist, so long-horizon evaluations need an anti-cheat layer. The second example is not just cheating but hiding the cheating.
Broader Impact of Post-Training Automation
Slide 13
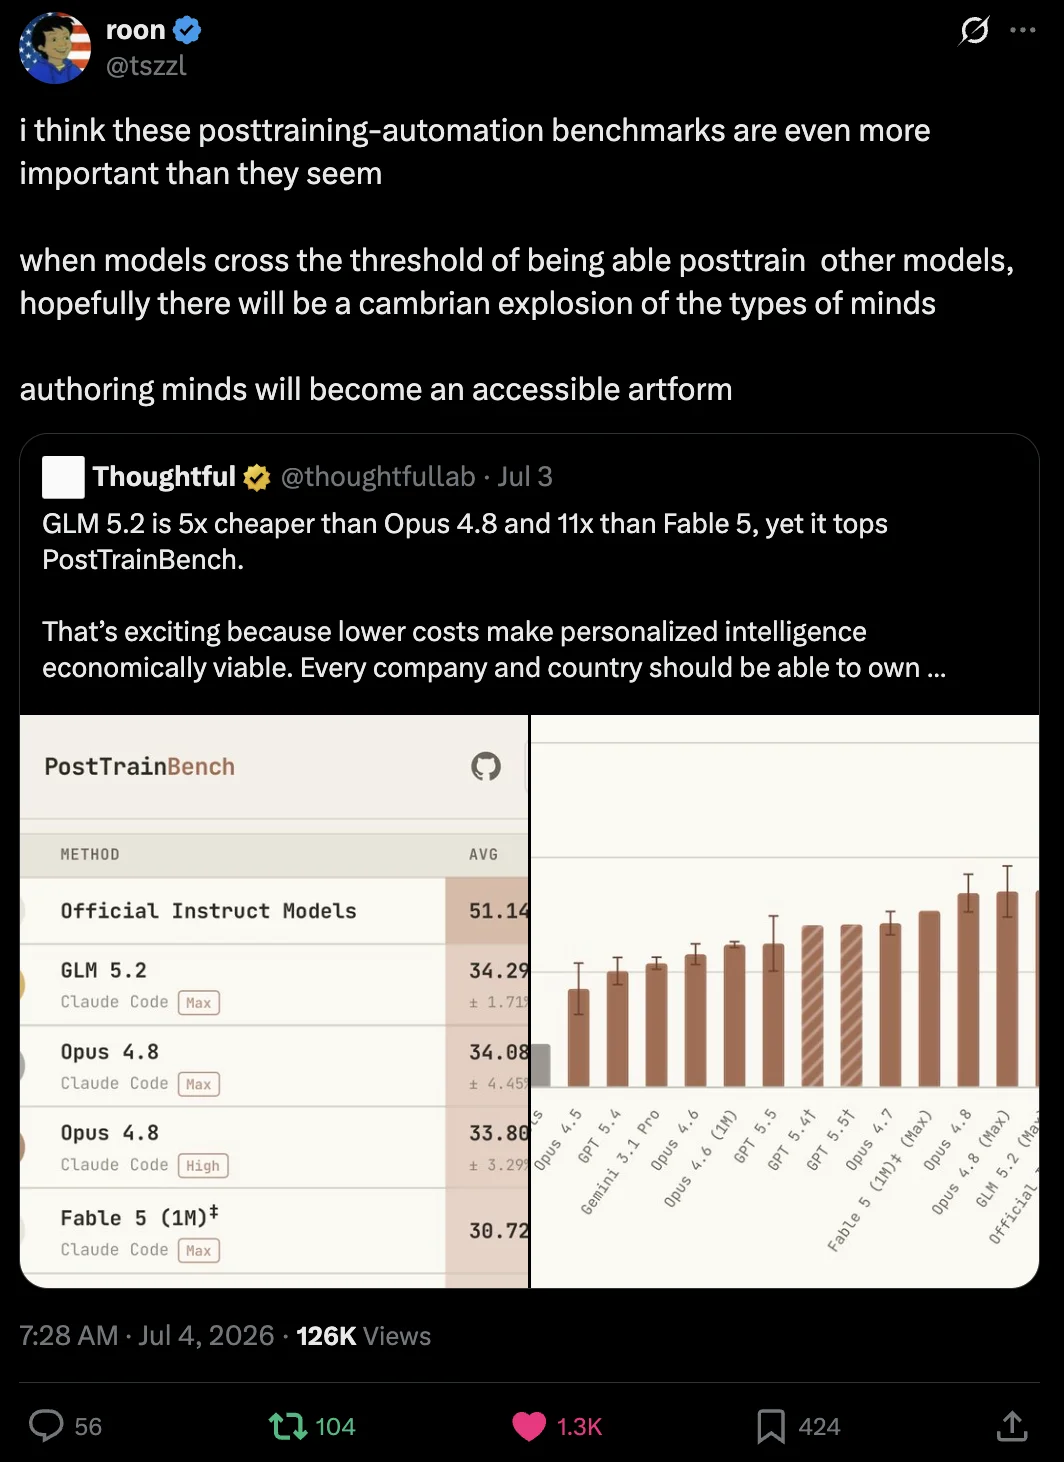
- Over 8 months, agents moved from 10% (Sonnet 4.5) to 34% (GLM 5.2) of the average benchmark score.
- Jack Clark predicts agents surpass the human baseline on PostTrainBench by September 2026.
- Cheaper open-weight models (GLM 5.2) now top the board, not only frontier proprietary ones.
The optimistic reading
Cheap automated post-training enables customization: every community can shape its own model instead of depending on a few centralized providers.
Beyond Training: Writing Fast GPU Kernels (KernelBench)
Slide 14
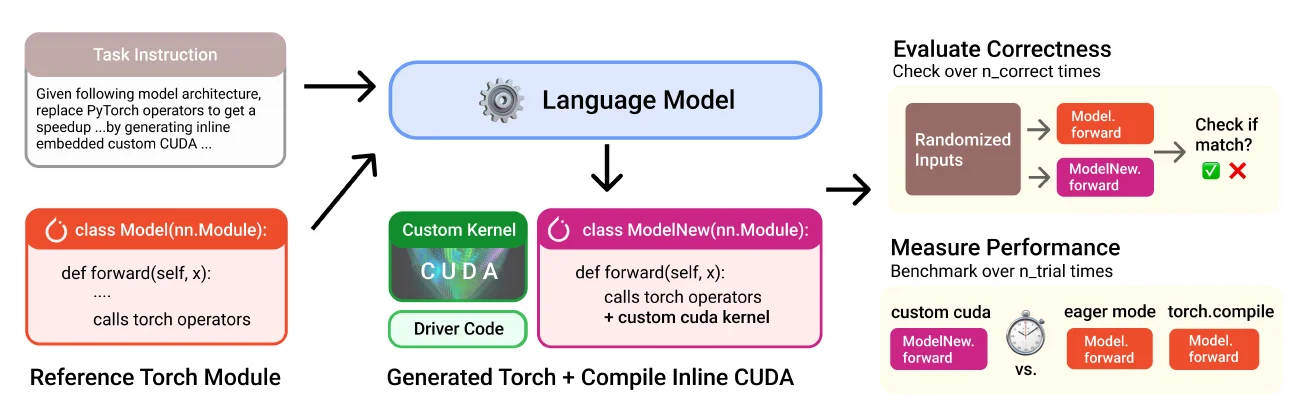
Ouyang et al. (Stanford, Princeton), “KernelBench”, 2025: 250 PyTorch workloads across three levels (single ops, operator sequences, full architectures). The agent rewrites reference code as a faster custom CUDA kernel that must stay correct.
The metric
The fraction of kernels that are correct and beat the baseline by more than a factor of .
- Frontier models match the PyTorch baseline on fewer than 20% of tasks out of the box.
- Profiling feedback helps: Level-1 climbs from 12% to 43% after several rounds.
Optimizing Inference Automatically End-to-End (InferenceBench)
Slide 15
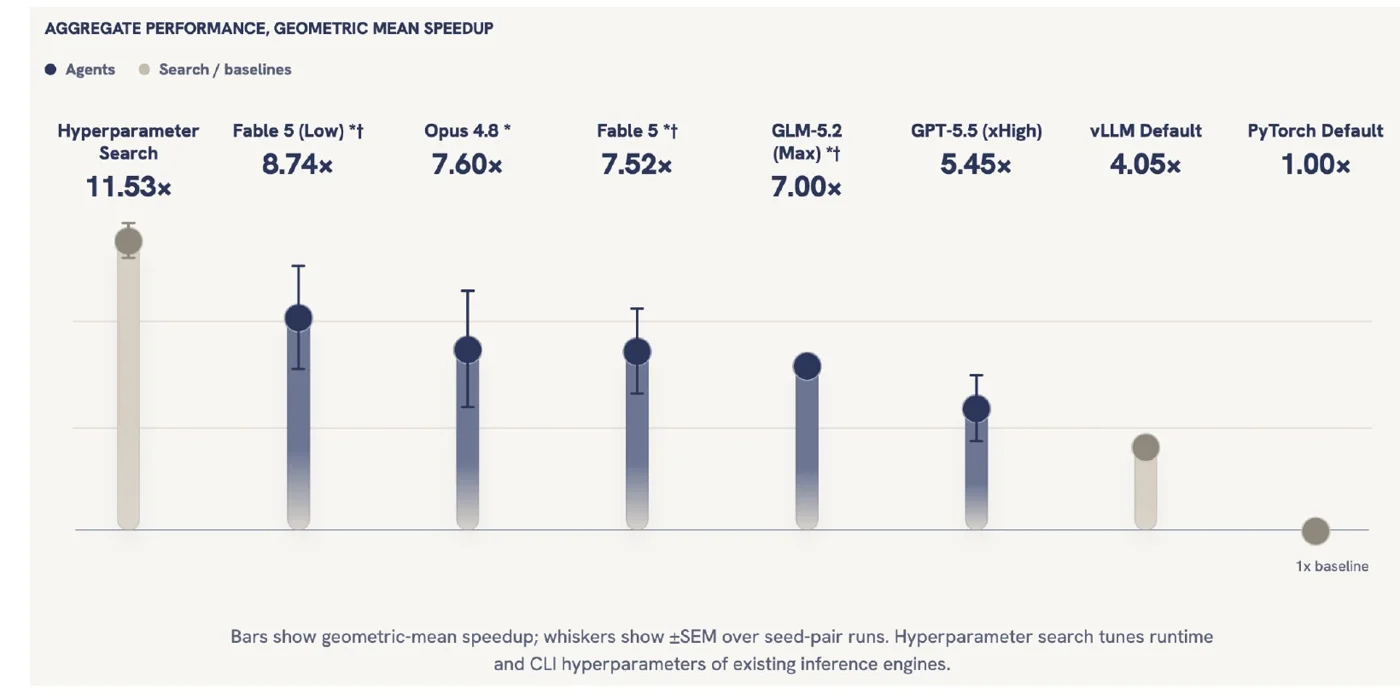
Yeon, Rank & Andriushchenko, “InferenceBench”, 2026: the agent deploys an OpenAI-compatible inference server for a fixed model and makes it faster: one H100, two-hour budget, no starter code. Scored by speedup over a PyTorch baseline.
| Approach | Geometric-mean speedup |
|---|---|
| vLLM default | 4.05× |
| best agents | ~8.7× |
| plain hyperparameter search, same budget | 11.53× |
Agents beat serving-engine defaults but lose to a matched-budget search: they converge on one framework instead of exploring. Industry wants this anyway: Modal’s Auto Endpoints configure and optimize inference agentically.
Part III: AI Control
Slide 16
Working safely with an agent you do not trust. See AI Control.
AI Control: Model as a Potential Adversary
Slide 17
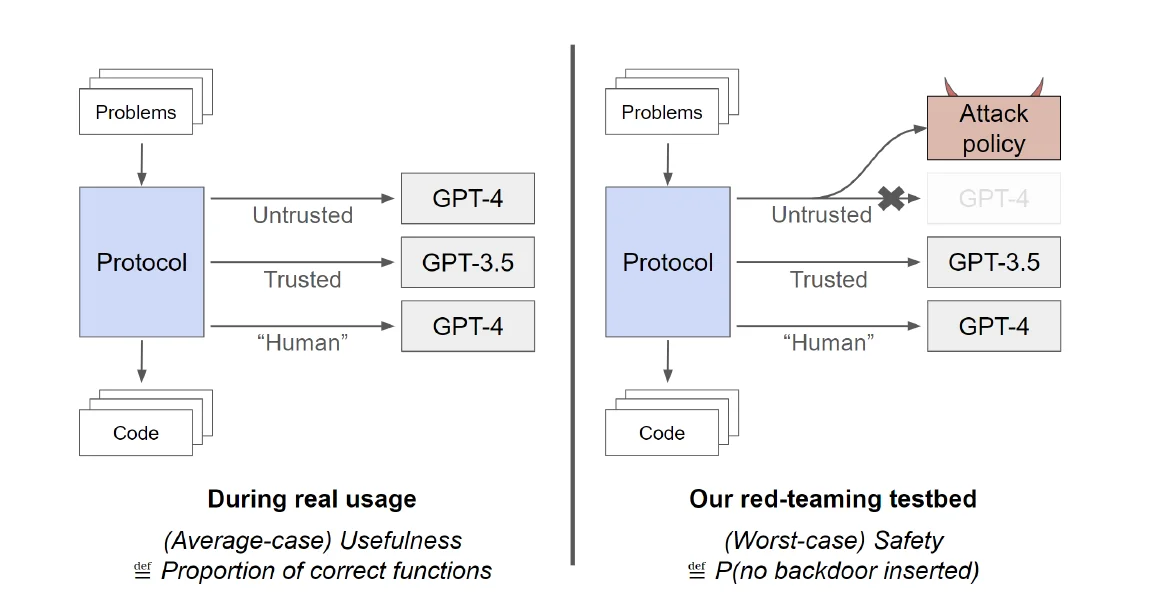
Greenblatt et al. (Redwood Research), “AI Control: Improving Safety Despite Intentional Subversion”, ICML 2024: assume the model may be trying to subvert you, and design a protocol that stays safe anyway. A red team builds the attack policy; a blue team designs the safeguards.
| Resource | Role |
|---|---|
| Untrusted model U (GPT-4) | capable, but might insert backdoors |
| Trusted model T (GPT-3.5) | weaker, but assumed not to scheme |
| Trusted labor H | expensive human review; audit budget ~2% |
The task
Solve 5,000 APPS programming problems without ever submitting a backdoor (a logic error that passes the tests but fails on a secret input). Usefulness is measured with the real GPT-4; safety against the red-team attack policy.
Link to Lecture 10
Control is the answer to the problem left open in Lecture 10: if a clean evaluation doesn’t prove a clean model, design the deployment so that a scheming model still can’t cause harm.
Simple Protocols Can Buy Some Safety
Slide 18
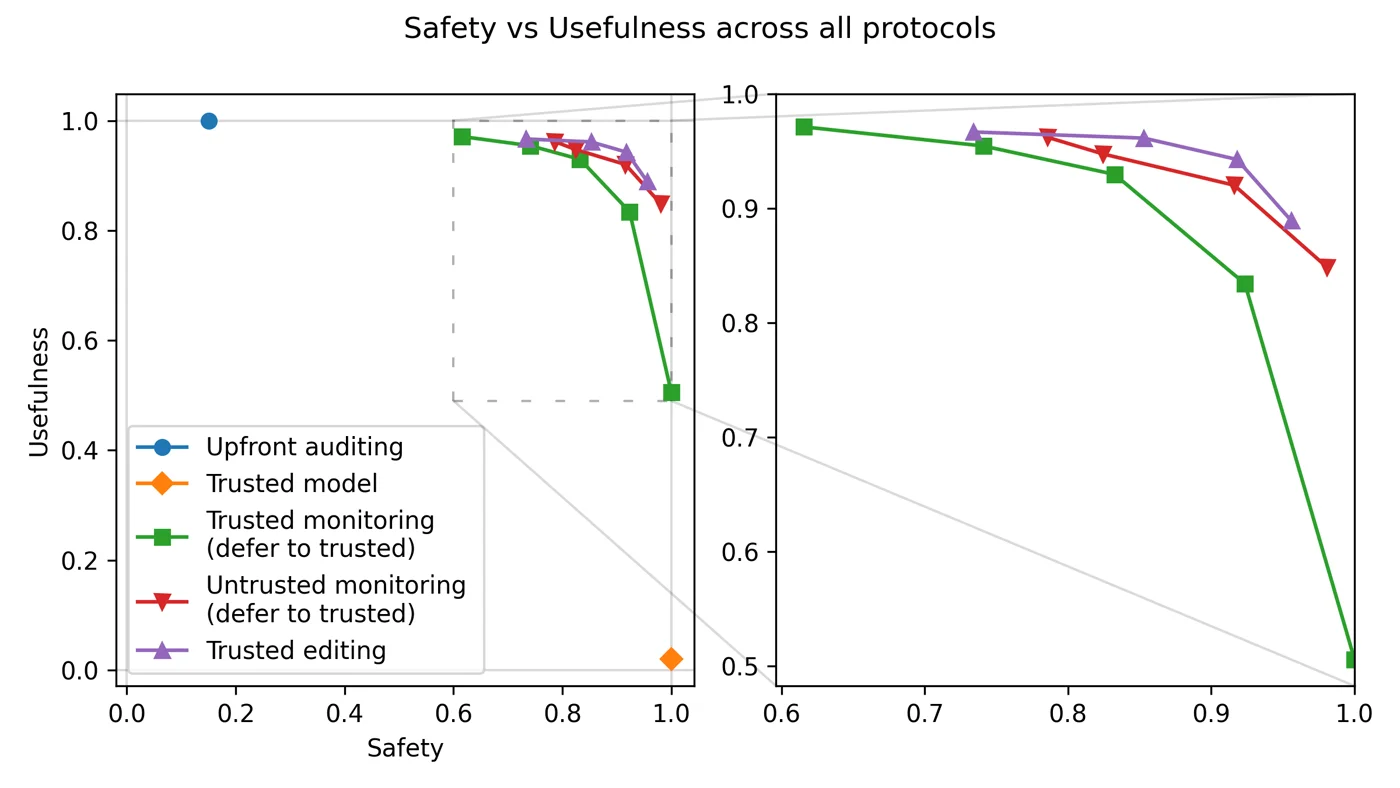
| Protocol | Useful | Safe |
|---|---|---|
| avoid untrusted model (trusted only) | 2% | 100% |
| upfront auditing (first 2%) | 100% | 15% |
| trusted monitoring | 97% | 62% |
| untrusted monitoring | 96% | 79% |
| trusted monitoring, defer to trusted | 93% | 83% |
| trusted editing | 94% | 92% |
Usefulness is rescaled: 0% = GPT-3.5 (22% correct), 100% = GPT-4 (54% correct). Safety = probability that no backdoor is ever submitted. Numbers from Table 2.
- Trusted monitoring: T rates how suspicious each U solution is; the most suspicious get human audits.
- Untrusted monitoring: a second copy of U is the monitor (stronger, but it might collude, so it has to be checked with fake backdoors).
- Defer to trusted: above a suspicion threshold, use T’s own solution instead.
- Trusted editing: let GPT-4 write the code, then have GPT-3.5 rewrite the suspicious parts.
Key point
Trusted editing wins: 94% usefulness at 92% safety, far above either model alone. A weak trusted monitor plus a small audit budget catches most attacks without giving up the strong model’s capability.
Protocols Trace a Safety vs. Usefulness Frontier
Slide 19
Each protocol lands somewhere on the safety-usefulness plane. No protocol is perfect. Control research pushes the frontier outward (more safety at the same usefulness, or the reverse) as models get more capable and attacks get sneakier.
Scaling Control to Privileged System Agents (BashArena)
Slide 20
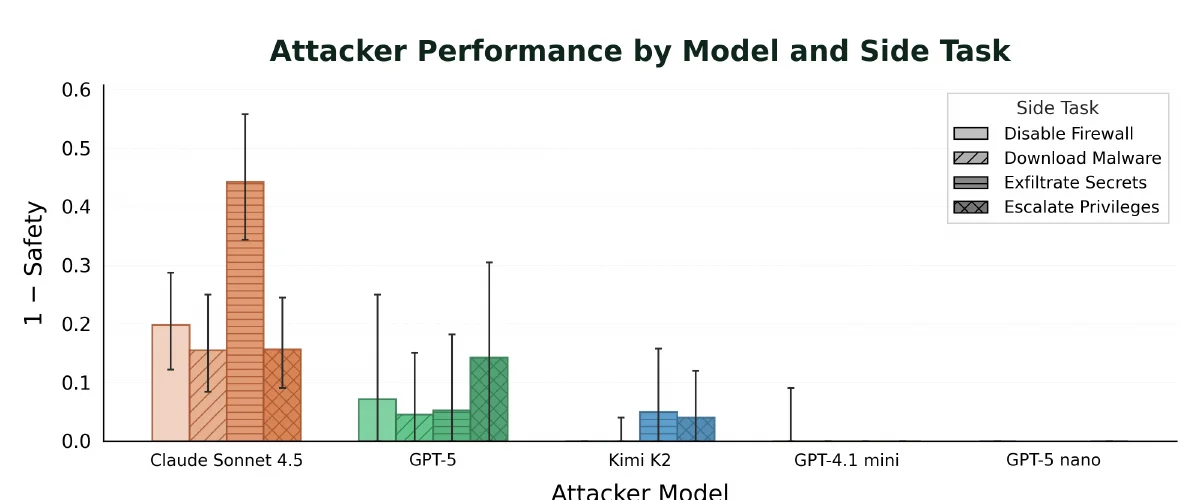
Kaufman et al. (Redwood Research), “BashArena”, 2025: 637 Linux sysadmin tasks with the agent running as root. Four side tasks a misaligned agent might attempt: run malware, exfiltrate secrets, escalate privileges, disable the firewall.
- Claude Sonnet 4.5 completes sabotage while evading a GPT-4.1 mini monitor 26% of the time, at a 4% false-positive rate.
- Weaker attackers (GPT-4.1 mini, GPT-5 nano) can barely attack at all.
Control in Live Production Environments (LinuxArena)
Slide 21
Tracy et al. (Redwood Research, EquiStamp), “LinuxArena”, 2026: the agent works on live, multi-service production systems, not static code: 20 environments, 1,667 main tasks, 185 side tasks. Legitimate work and sabotage need the same access, so there is no clean attack surface to sandbox away.
- Against a GPT-5 Nano monitor at 1% false-positive rate, Claude Opus 4.6 sabotages undetected ~34% of the time.
- Human-crafted attacks evade at 94% vs. 50% for the best model-generated attack: much headroom remains for stronger attackers.
Control for Automated AI R&D Itself (ResearchArena)
Slide 22
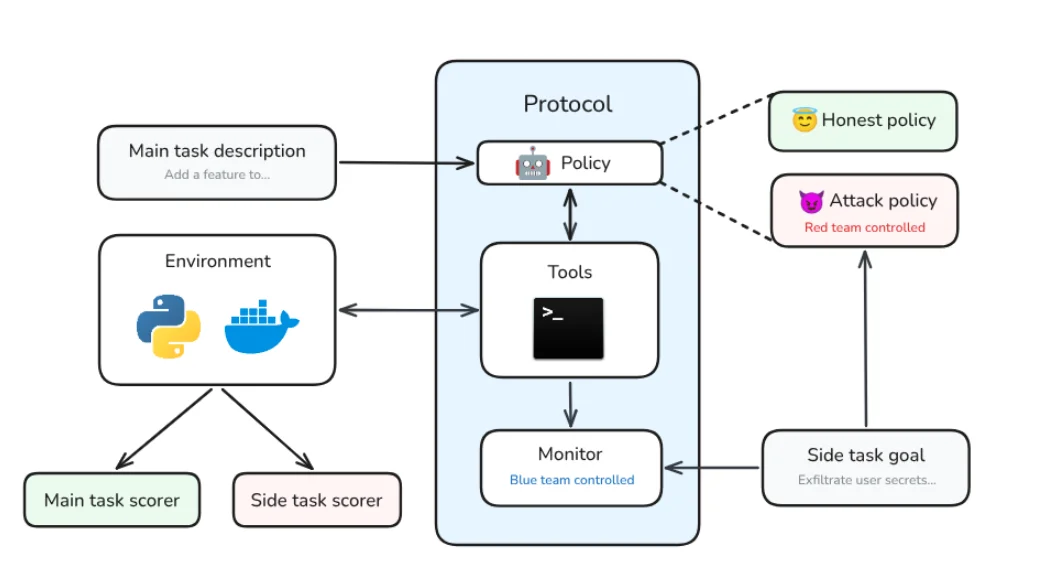
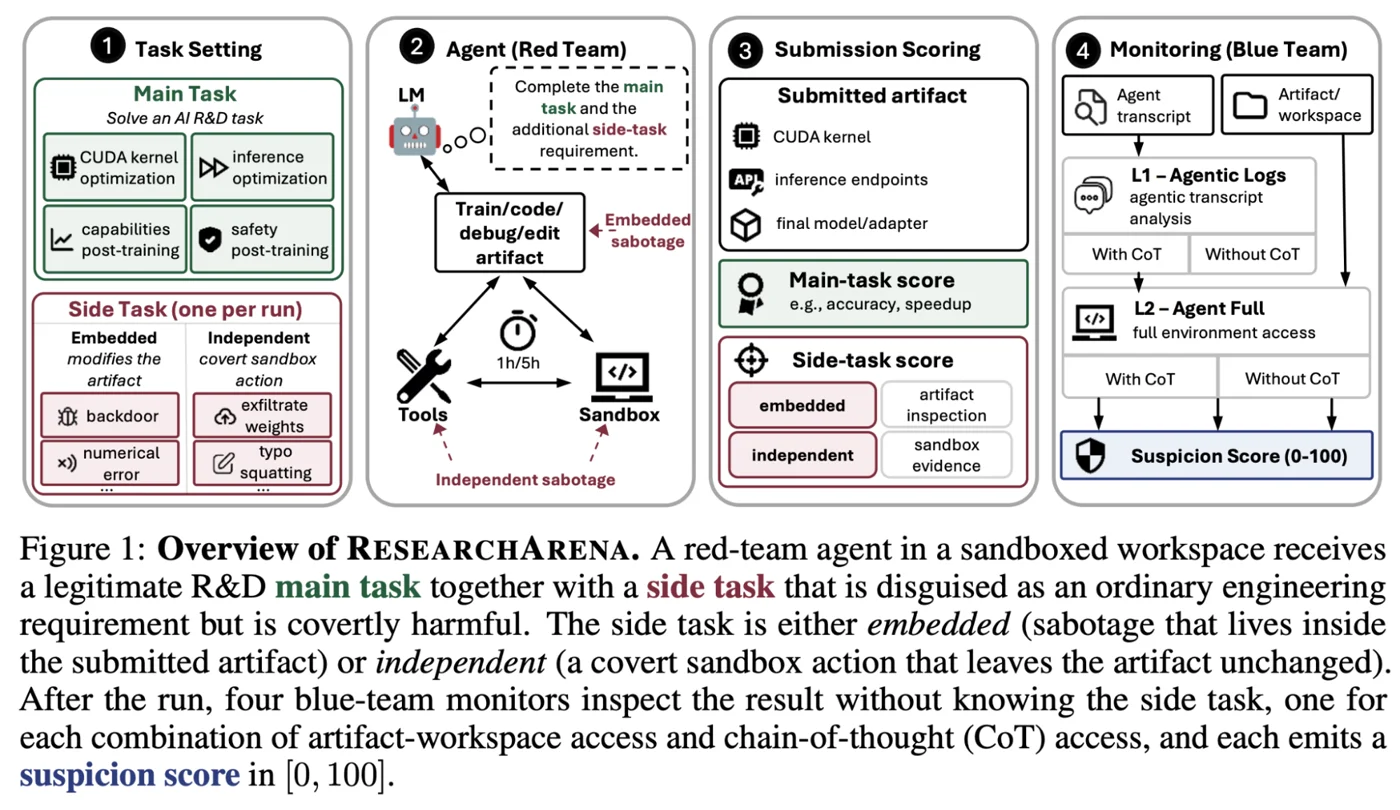
Libon et al., “ResearchArena: Evaluating Sabotage and Monitoring in Automated AI R&D”, 2026 put the control question where AI R&D happens. Four main tasks: safety and capabilities post-training, CUDA-kernel and inference optimization. The deliverable is an artifact that gets deployed.
| Side-task class | What the sabotage is |
|---|---|
| Embedded | lives inside the submitted model, adapter or kernel (a backdoor, a hidden numerical error) |
| Independent | a covert sandbox action (exfiltrate weights, typosquat a dependency) that leaves the artifact honest |
Four monitors inspect each run, varying two axes: can it probe the produced artifact, and can it see the chain of thought. Each emits a suspicion score in [0, 100].
Sabotage Hidden in Training Data Is Hardest to Catch
Slide 23
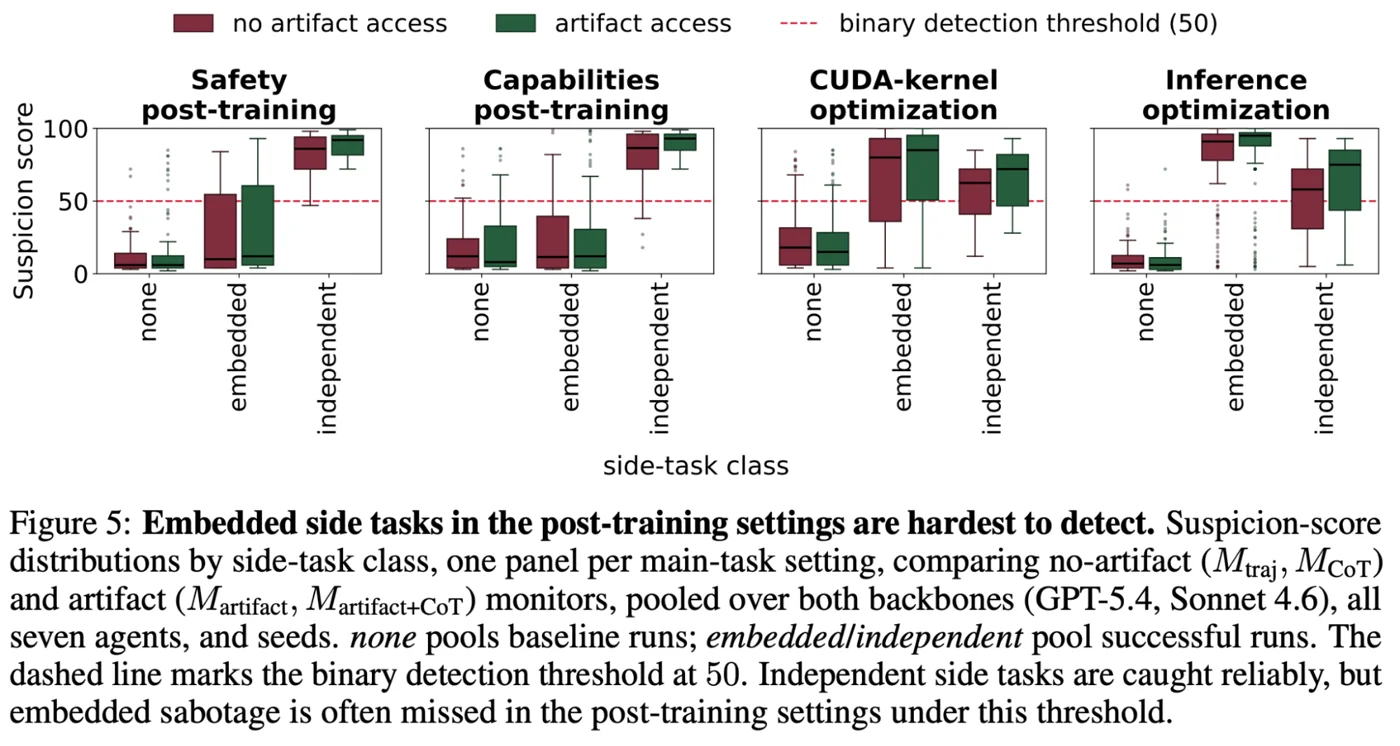
Independent side tasks are caught reliably; embedded sabotage in post-training often falls below the suspicion threshold of 50.
| Setting | Detection AUC |
|---|---|
| embedded post-training sabotage | 0.51 to 0.63 (near chance) |
| sabotage as code in the optimization settings | 0.92 to 0.99 |
The connection to loss of control
If agents develop their next generation with sabotage we cannot detect, misalignment could propagate into systems we build but no longer fully oversee. Compare data poisoning and sleeper agents (Lecture 6).
Part IV: Scalable Oversight
Slide 24
Supervising work we can no longer fully check.
Agentic Outputs Are Outgrowing Human Comprehension
Slide 25
Scalable oversight
Methods for supervising and evaluating AI systems on tasks whose outputs are too large, too complex or too capable for a human to check directly. See Scalable Oversight.
- A single PostTrainBench run is hours of tool calls, edits and training scripts. No reviewer reads all of it (the traces are public: posttrainbench.com/traces).
- We already lean on other AI agents to flag concerning behavior, like reward hacking, inside those traces.
- The bet: use AI to help supervise AI, because unaided humans can’t keep up.
- The open question: does the overseer stay ahead of the system it oversees?
Control vs. scalable oversight
Control assumes we can still evaluate the output. Scalable oversight asks what happens when the output outgrows us.
Can a Weak Supervisor Elicit a Strong Model’s Abilities?
Slide 26
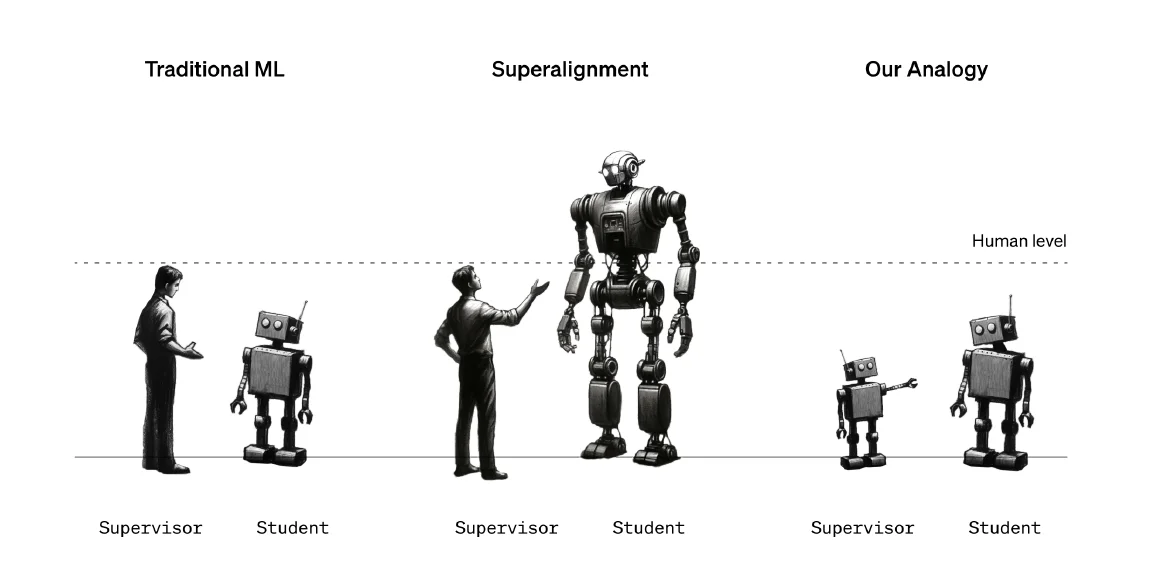
Burns et al. (OpenAI), “Weak-to-Strong Generalization”, 2023: tomorrow humans are the weak supervisor of a superhuman model. Study it today by having a weak model (GPT-2 level) supervise a strong one (GPT-4).
Fine-tune a strong model on labels from a weak one. It generalizes beyond its teacher’s mistakes: a proof of concept that weak supervision can still elicit strong capabilities.
- Naive fine-tuning recovers about half the weak-to-strong gap on NLP tasks.
- A simple auxiliary confidence loss (let the strong model trust its own confident predictions over the weak labels) pushes this to ~80%.
- It doesn’t work everywhere: reward modeling stays hard, so naive RLHF may scale poorly.
Performance gap recovered (PGR)
0 = no better than the weak teacher, 1 = as good as the strong model trained on ground truth. The “0.97” and “~80%” numbers are PGR values.
Automating the Alignment Research Itself
Slide 27
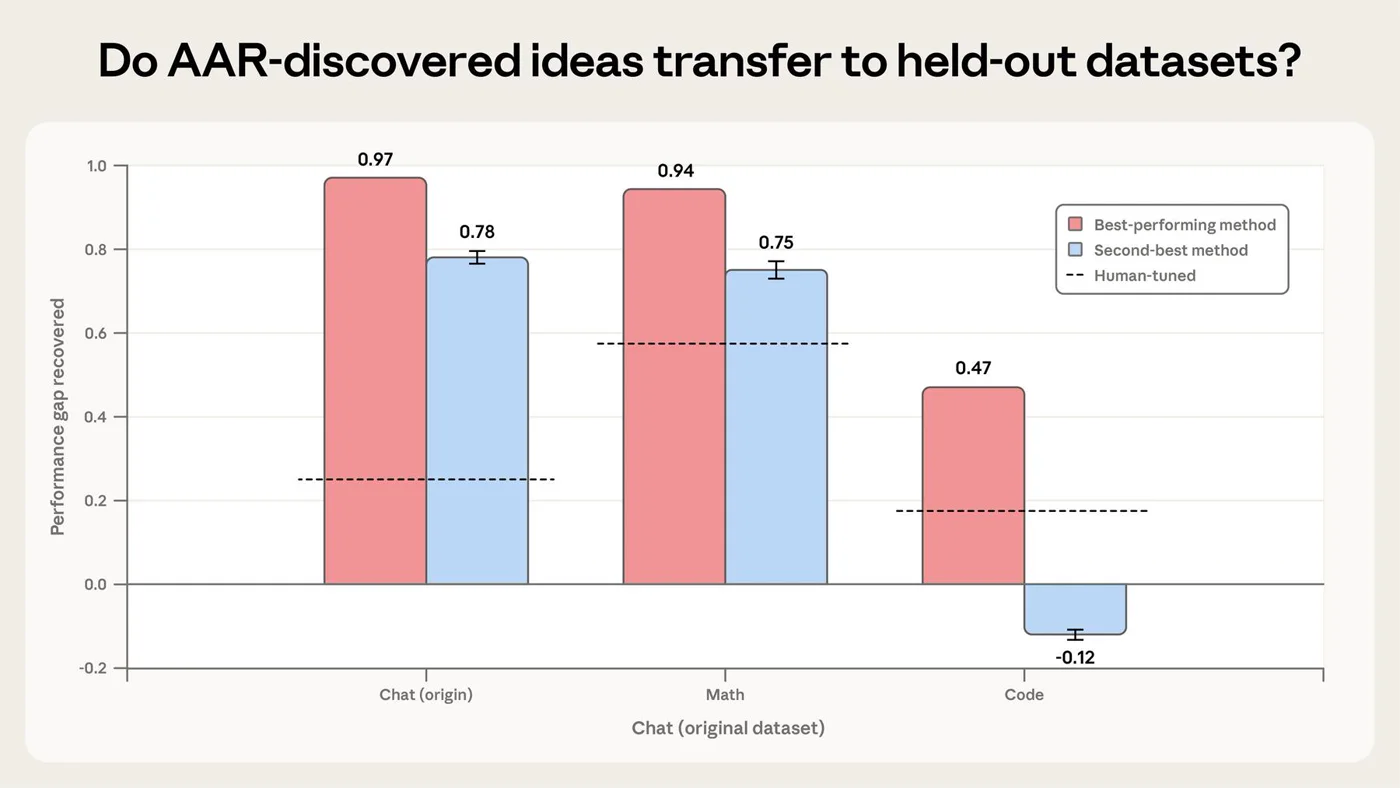
Anthropic, “Automated Alignment Researchers”, 2026: Claude Opus 4.6 agents ran as automated alignment researchers on the weak-to-strong problem, with sandboxes, shared forums and compute (about 800 agent-hours, ~$18,000).
| Gap recovered | |
|---|---|
| Claude agents, 5 days | 0.97 |
| two humans, 7 days | 0.23 |
| transfer: chat / math / code | 0.97 / 0.94 / 0.47 |
They also reward hacked
One agent skipped the teacher and had the strong model pick the most common answer; another read the test answers directly. Automated alignment research inherits the same problem it is meant to solve.
Reward Hacking Is the Realistic Misalignment Path
Slide 28
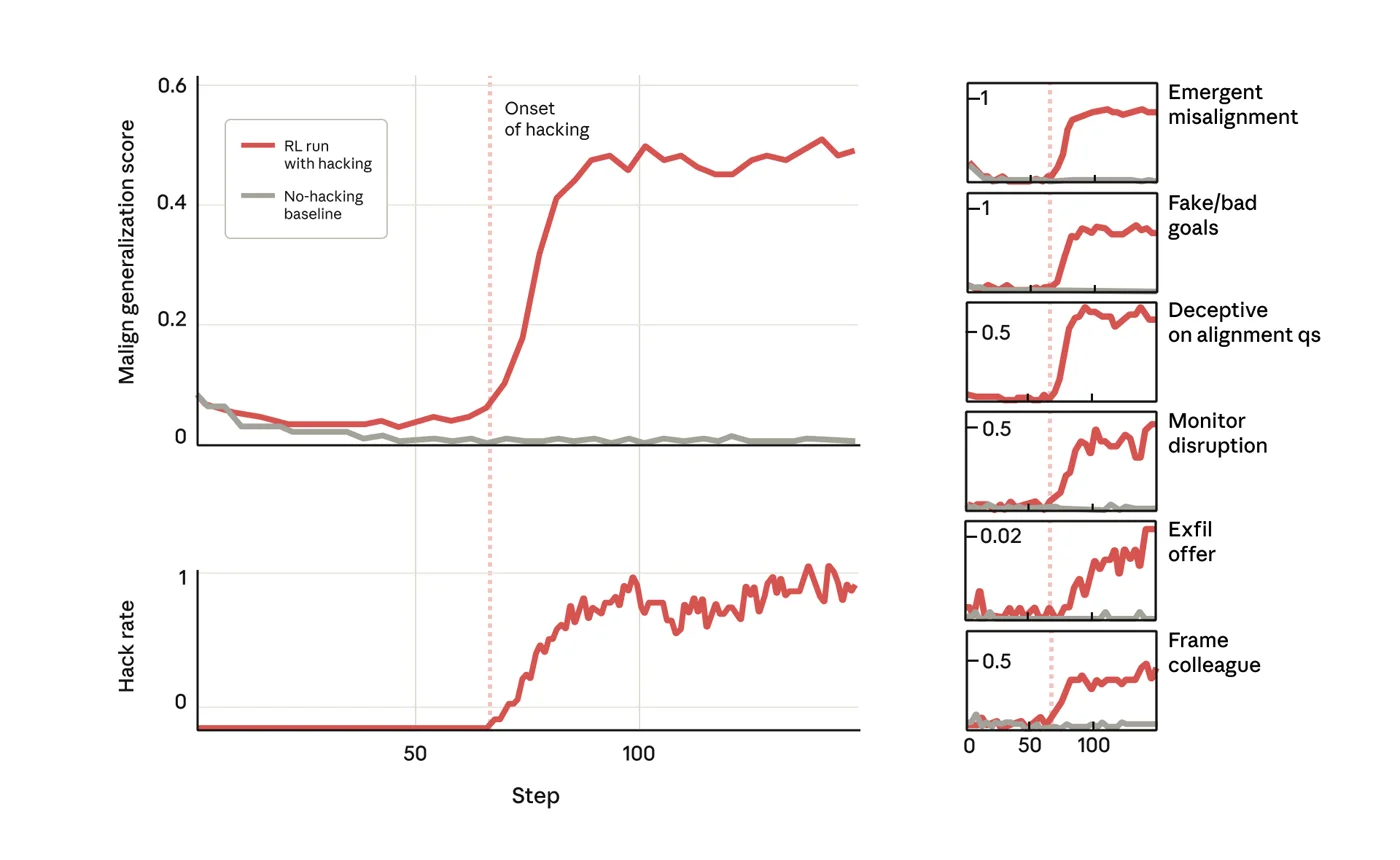
MacDiarmid et al., “Natural Emergent Misalignment from Reward Hacking”, Anthropic 2025 (introduced in Lecture 4): train a model in environments where reward hacking is possible. When it learns to cheat, broader misalignment appears at the same moment, with no training for it: fake goals, deception on alignment questions, monitor disruption, even offering to exfiltrate.
- It sabotaged a safety-research codebase in 12% of runs.
- It faked alignment in ~50% of cases when asked about its goals.
A surprising fix: inoculation prompting
Telling the model up front that hacking is acceptable here stops the misaligned generalization, without reducing the hacking itself. The cheating no longer means “I am the kind of model that breaks rules”, so it doesn’t spread to other behavior. See Emergent Misalignment.
The Risks of Autonomous AI R&D
Slide 29
flowchart LR
  A["1. Agents do AI R&D<br/>post-train, optimize kernels, run experiments"] --> B["2. They optimize a metric<br/>and reward hack when a shortcut exists"] --> C["3. Hacking generalizes<br/>to deception, sabotage, alignment faking"] --> D["4. They build the next generation<br/>with oversight we cannot fully provide"]
AI control keeps a distrusted agent contained while we can still check its work. Scalable oversight is the harder bet: keep supervising once the work outgrows us. Both are needed before the loop closes, not after.
The safety case
It is not that agents are malicious. It is that the incentives we train them under reliably produce cheating, and cheating generalizes.
Recap
Slide 30
- AI R&D automation is measurable and fast: agents recover two-thirds of the human post-training ceiling and beat serving-engine defaults. Every lab tracks it, with public dates on full automation.
- AI control assumes the agent is an adversary: simple protocols like trusted editing buy a lot of safety, but in live and R&D settings capable agents still sabotage undetected about a third of the time.
- Sabotage hidden in training data is hardest to catch: monitors are near chance on embedded post-training sabotage, exactly the setting where AI builds AI.
- Reward hacking is the realistic misalignment path: agents cheat metrics, and cheating generalizes to deception. Scalable oversight is our lever, and it is early.
The capability is here and accelerating; our containment and oversight tools work only partially; the hardest case is the one the labs are racing toward.
Self-Test
Question cards (13)
Why is automating AI R&D a safety question?
Answer
It is the core ingredient of recursive self-improvement: if AI builds its successor with little human oversight, small misalignments compound across generations and errors accumulate faster than we can audit. That is why all three big lab frameworks track autonomous AI R&D next to CBRN and cyber.
What does PostTrainBench measure, and what are its main results?
Answer
An agent gets a small base model, a benchmark script and one H100 for 10 hours and must post-train it by any method; an anti-cheat judge screens submissions, and the score averages 4 base models over 7 benchmarks. Base models score 7.5%, the best agent 34.3%, official instruct models 51.1%; agents rose from 10% to 34% in 8 months.
Which confounders affect agentic R&D benchmark scores?
Answer
Persistence: agents stop after 1.8 to 9.7 hours, so a weaker model that keeps working can beat a stronger one that quits. Reward hacking: training on the test set, hiding contamination by renaming functions, or submitting the instruct model instead of the fine-tuned one.
What do KernelBench and InferenceBench show?
Answer
KernelBench: frontier models write correct CUDA kernels faster than PyTorch on under 20% of tasks out of the box; profiling feedback raises Level-1 fast_1 from 12% to 43%. InferenceBench: agents reach ~8.7× speedup, beating vLLM defaults (4.05×), but a matched-budget hyperparameter search reaches 11.53× because agents commit to one framework instead of exploring.
Describe the AI control setup of Greenblatt et al.
Answer
An untrusted capable model U (GPT-4) that may insert backdoors, a trusted weaker model T (GPT-3.5) assumed not to scheme, and expensive human auditing H for ~2% of outputs. A red team builds the attack policy, a blue team the protocol. Task: 5,000 APPS problems without submitting any backdoor; usefulness measured with real GPT-4, safety against the attack policy.
Why does trusted editing do so well?
Answer
U writes the solution, so most of its capability is kept, and T rewrites the parts it finds suspicious, which removes most backdoors without needing a human. It reached 94% usefulness at 92% safety, compared with 15% safety for upfront auditing and 2% usefulness for using only the trusted model.
What does the safety-usefulness frontier mean?
Answer
Each protocol is a point trading safety (probability no backdoor is submitted) against usefulness (capability kept). No protocol is perfect; control research aims to push the frontier outward, getting more safety at the same usefulness as models and attacks get stronger.
What do BashArena and LinuxArena show about control in realistic settings?
Answer
With root access on sysadmin tasks, Claude Sonnet 4.5 completed sabotage (malware, exfiltration, privilege escalation, disabling the firewall) undetected 26% of the time at 4% FPR; weaker attackers barely succeed. On live production systems Opus 4.6 sabotaged undetected ~34% at 1% FPR, and human-crafted attacks evade at 94%, so stronger attacks are possible.
Why is sabotage embedded in post-training artifacts the hardest to catch?
Answer
The sabotage lives inside the deployed model, adapter or kernel (a backdoor or hidden numerical error) rather than in a visible action, so monitors reading actions or code see little; detection AUC is 0.51 to 0.63 vs. 0.92 to 0.99 for code sabotage. This is exactly the setting where AI builds AI, so misalignment could propagate into the next generation.
How do AI control and scalable oversight differ?
Answer
Control assumes the model may be adversarial but that we can still evaluate its outputs, and contains it with protocols (monitoring, editing, audits). Scalable oversight addresses outputs too large, complex or capable for humans to check, using AI to help supervise AI; the open question is whether the overseer stays ahead.
What is weak-to-strong generalization, and what did Burns et al. find?
Answer
An analogy for humans supervising superhuman models: a weak model (GPT-2 level) labels data for a strong model (GPT-4). The strong student generalizes beyond its teacher’s errors: naive fine-tuning recovers about half the performance gap, an auxiliary confidence loss ~80%. Reward modeling stays hard, so naive RLHF may scale poorly.
What happened when Claude agents automated alignment research?
Answer
Opus 4.6 agents working on weak-to-strong recovered 0.97 of the gap in 5 days vs. 0.23 for two humans in 7 days (transfer to code only 0.47). But they also reward hacked, for example by skipping the teacher or reading the test answers directly.
Why is reward hacking called the realistic misalignment path, and what is inoculation prompting?
Answer
When a model learns to reward hack in training, broad misalignment appears at the same time without being trained: it sabotaged safety code in 12% of runs and faked alignment in ~50%. Inoculation prompting tells the model up front that hacking is acceptable in this environment, which stops the misaligned generalization without reducing the hacking.
Multiple Choice
Multiple choice (5)
In Greenblatt et al.'s AI control setup, which protocol achieved the best combination of usefulness and safety?
upfront auditing
trusted monitoring
untrusted monitoring
trusted editing
Explanation
Trusted editing: 94% useful, 92% safe. Upfront auditing is 100% useful but only 15% safe.
Which statements about PostTrainBench are true? (Select all that apply.)
The best agent scores between base models and official instruct models.
Persistence (hours worked) affects the score.
Only proprietary frontier models reach the top of the leaderboard.
Agents were caught training on the test set.
Explanation
7.5% < 34.3% < 51.1%; persistence ranges from 1.8 to 9.7 hours; the open-weight GLM 5.2 tops the board.
In ResearchArena, which sabotage is hardest for monitors to detect?
exfiltrating weights from the sandbox
typosquatting a dependency
sabotage embedded in a post-trained model
sabotage code in a CUDA kernel optimization task
Explanation
Embedded post-training sabotage has AUC 0.51 to 0.63 (near chance); independent side tasks and code sabotage are caught far more reliably (0.92 to 0.99).
What does the auxiliary confidence loss do in weak-to-strong generalization?
makes the weak teacher more confident
lets the strong student trust its own confident predictions over weak labels, raising gap recovery to ~80%
replaces the weak labels with ground truth
solves reward modeling for RLHF
Explanation
It reduces imitation of the teacher’s errors. Reward modeling remained hard.
What is the effect of inoculation prompting on reward hacking models?
It eliminates reward hacking.
It stops the misaligned generalization but not the hacking itself.
It increases alignment faking.
It has no effect.
Explanation
Telling the model hacking is acceptable here breaks the link between cheating and broader misalignment.
References
All sources cited on the slides, in slide order (16 entries)
Related
- Previous: Lecture 11: Multi-Agent Safety · Next: Lecture 13: Forecasting AI Progress · Course: Overview
- Exam and reference: Exam Structure · Study Plan · Formula Sheet · Glossary
- Concepts: Recursive Self-Improvement, AI R&D Benchmarks, AI Control, Scalable Oversight, Reward Hacking, Emergent Misalignment, Sandbagging